Jiashu Yang

Illustrated portrait of Jiashu Yang
杨佳澍Beijing, China

I work on open-world visual understanding and large-scale foundation models that connect language, vision, and action.

My current focus is world models and vision-language-action (VLA), with an emphasis on practical, deployable intelligence.

I lead Wenyuan Pavilion, an open-source community dedicated to Chinese-culture-centered language models.

I have pursued computer vision research with Yian Zhao and Chaoran Feng since 2023, and explored LLMs with Xuxin Cheng since 2024.

Currently

Qianli Technology (Afari)

Qianlima Talent Program

2026.06 – Present

I lead a PhD research intern team developing next-generation VLA architectures with Hefei Huang, Jianyu Zhang, and Zhiyuan Liang.

World models and VLA: representation learning, data, post-training, and reinforcement learning.

We welcome talented researchers to join us.

Meituan

Research Intern · Longcat Interaction Team · Beijing

2025.12 – 2026.05

Worked on ToB agentic RL for Table/Excel question answering. Led knowledge-graph-based data synthesis and developed Hindsight-guided Knowledge Distillation to reduce distillation steps and improve accuracy.

CASIA logoShanghai Jiao Tong University logo

CASIA & Shanghai Jiao Tong University

Institute of Automation, Chinese Academy of Sciences · Research Intern · 2023.11 – 2024.08

School of Artificial Intelligence, SJTU · Research Intern · 2025.07 – 2025.09

Developed EyeVLA for language-guided rotation and zoom, combining VLMs, 500 real-world examples, and RL post-training for robotic active perception.

ByteDance

Research Intern · Applications of LLMs · Beijing

2025.04 – 2025.07

Designed Deep Research data synthesis, supporting BrowseComp SOTA; contributed to LabelGPT video understanding and structured annotation.

IIAU Lab, Dalian University of Technology

Research Assistant

2024.05 – 2025.01

Multimodal document understanding with Prof. Huchuan Lu and Prof. Xu Jia.

  1. EvaGaussians: Event Stream Assisted Gaussian Splatting from Blurry Images

    W Yu, C Feng, J Tang, Jiashu Yang, X Jia, L Yuan, Y Tian

  2. Kongzi: A Historical Large Language Model with Fact Enhancement

    J Yang, N Wang, Y Zhao, C Feng, J Du, H Pang, Z Fang, X Cheng

  3. Tune-Your-Style: Intensity-tunable 3D Style Transfer with Gaussian Splatting

    Y Zhao, R Ye, R Zheng, Z Cheng, C Feng, J Yang, P Qiao, C Liu, J Chen

  4. Breaking the Vicious Cycle: Coherent 3D-GS from Sparse & Blurred Views

    Z Xu, C Feng, Y Li, J Zhao, J Yang, W Yu, L Yuan, Y Tian

  5. Look, Zoom, Understand: The Robotic Eyeball for Embodied Perception

    J Yang, Y Han, Y Xie, N Guo, W Lian

  6. AutothinkRAG: Complexity-Aware Control of Retrieval-Augmented Reasoning for Image-Text Interaction

    J Yang, C Zhang, A Wuerkaixi, X Cheng, C Liu, K Zeng, X Jia, X Cai

LongHorizonOS logo

LongHorizonOS

An OS-like exoskeleton for long-running agents, with time-sliced execution, gated restarts, and versioned progress graphs. Evaluated on the 46-task LongHorizonBenchmark, with ~2.4× fewer input tokens and reward parity or better on 37 of 42 tasks.

DocThinker logo

DocThinker

An all-in-one RAG system that builds structured, graph-based memory using knowledge graphs.

Wenyuan Pavilion logo

Wenyuan Pavilion

I lead an open-source research community focused on Ancient Chinese and literature, with language models and datasets.

BEng. in Artificial Intelligence

Dalian University of Technology

2022.09 – 2026.06

Sincerely looking for PhD positions for fall admission!

Table tennis. I enjoy the fast pace and tactical depth of the sport.

Martial arts. I am drawn to the discipline, tradition, and physical and mental cultivation.

WeChat

Scan to connect with Jiashu Yang.

WeChat QR code to connect with Jiashu Yang

请注明来意和姓名

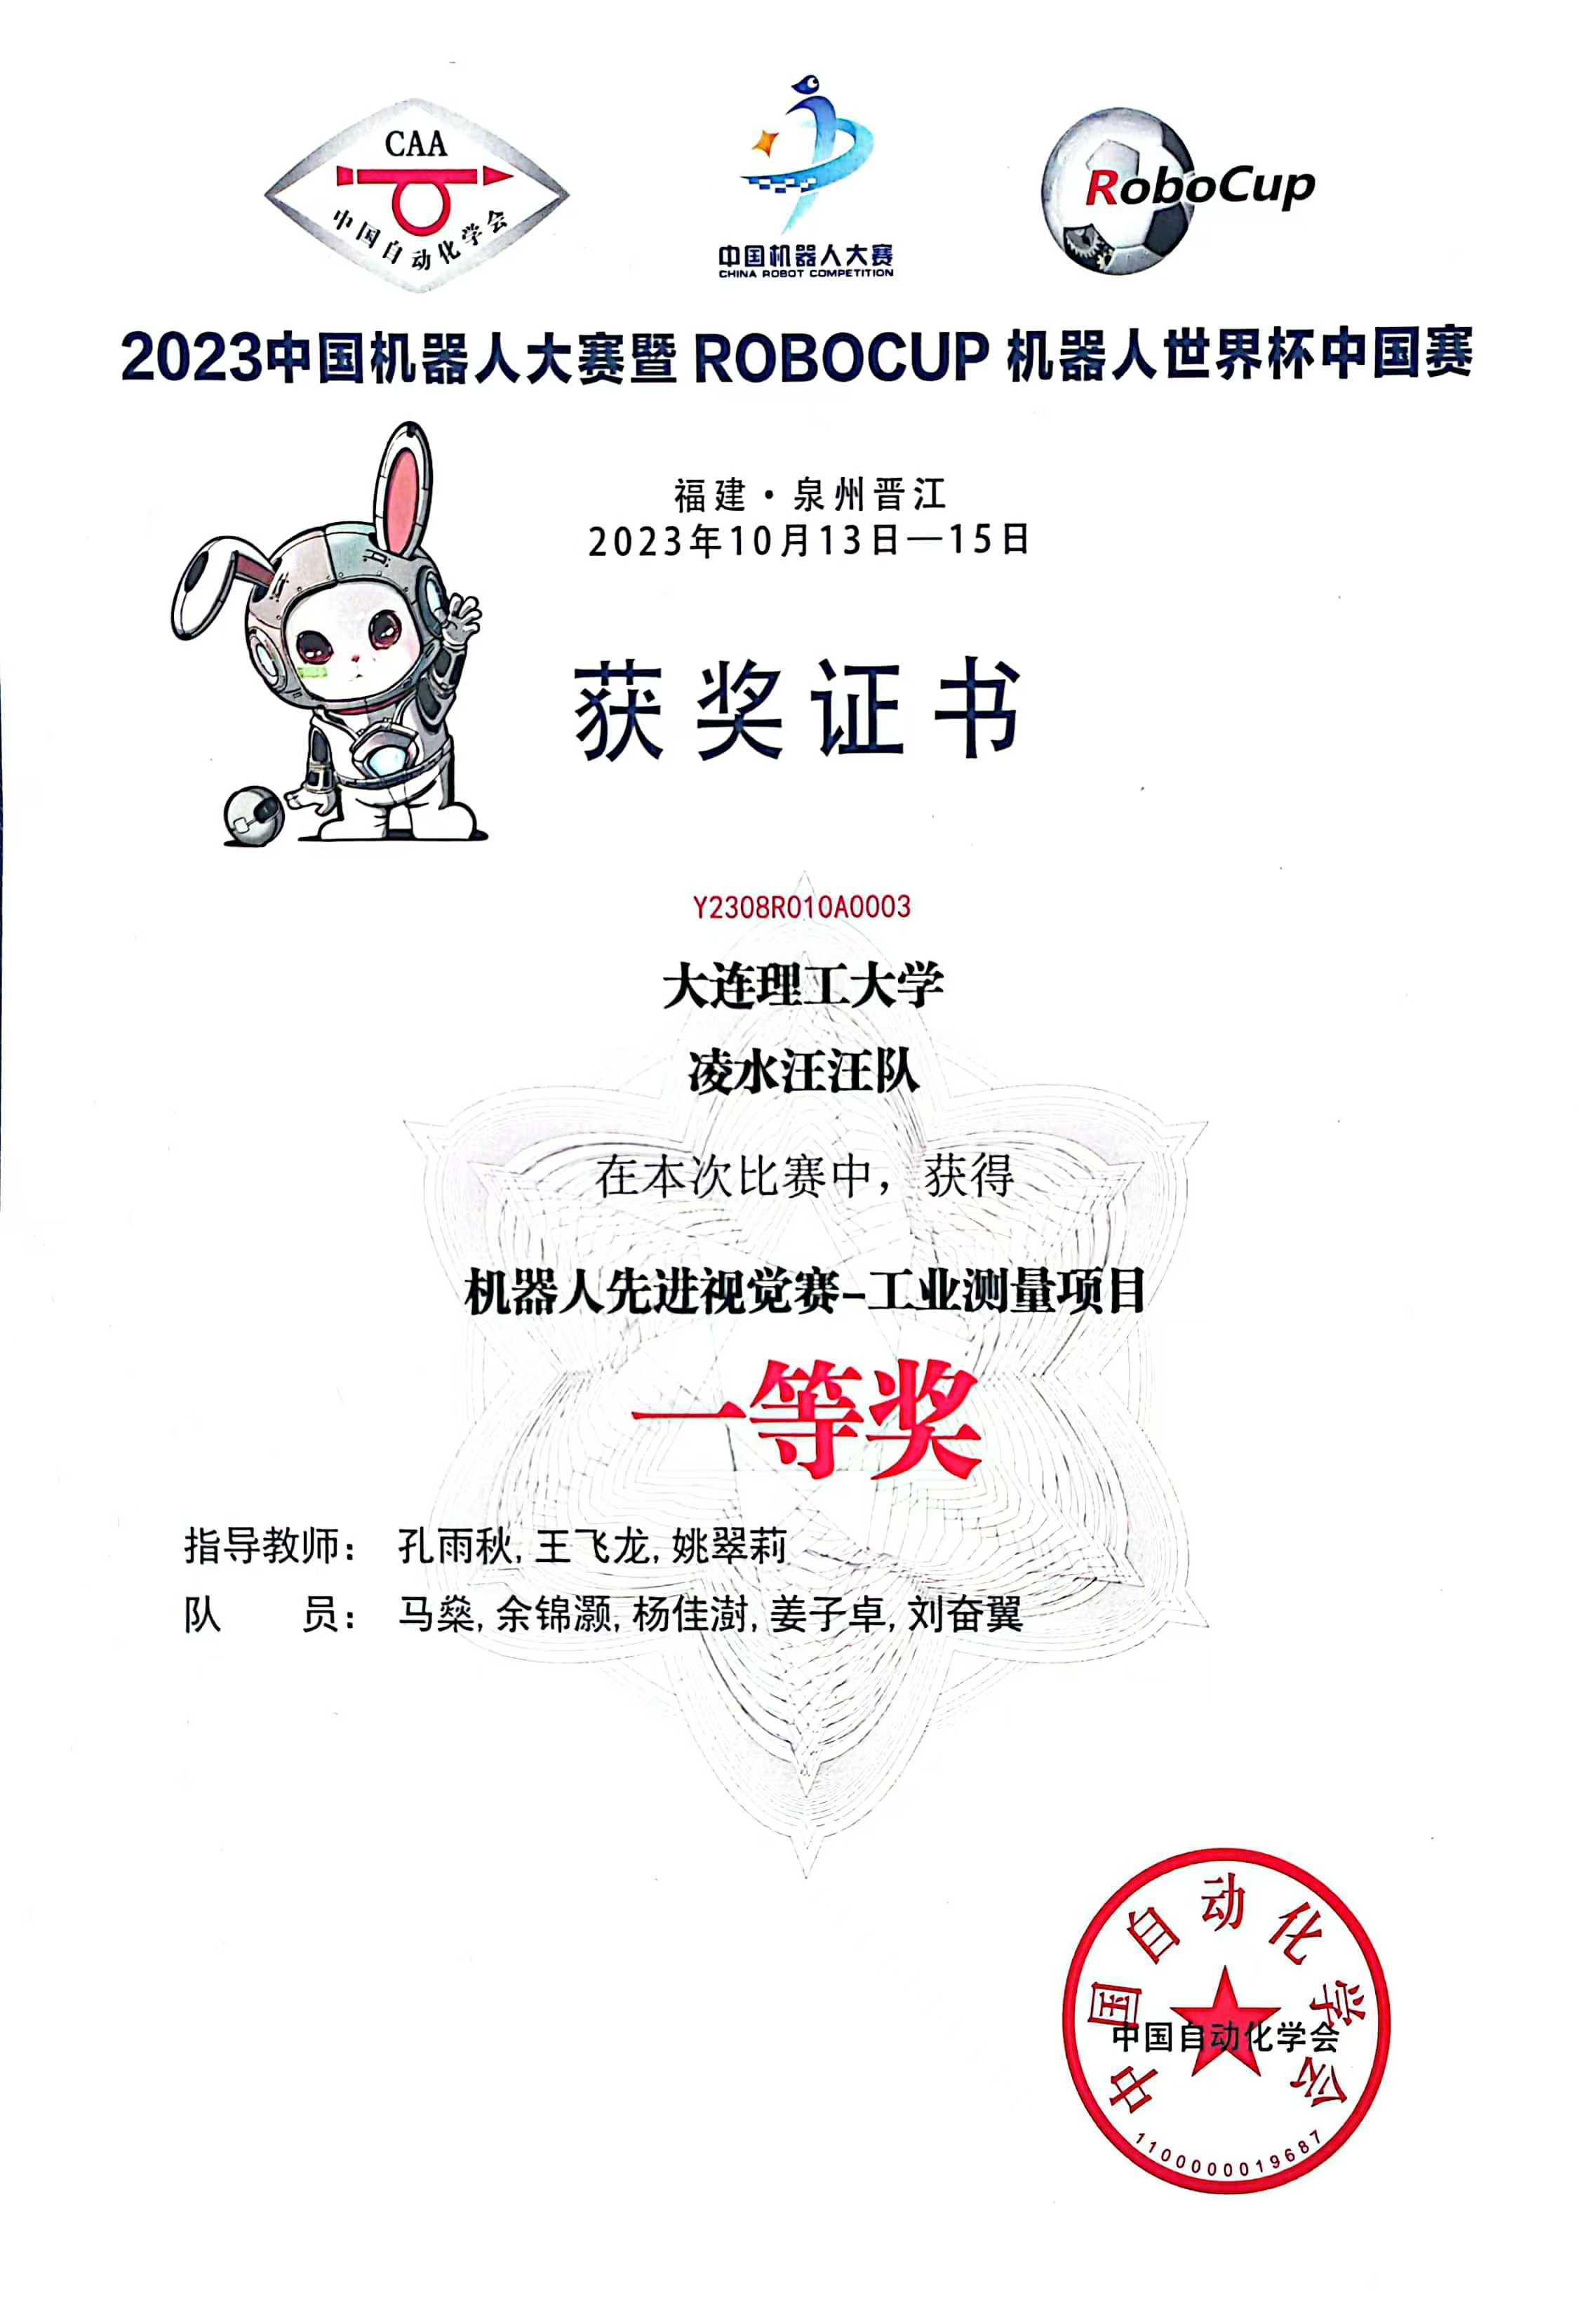
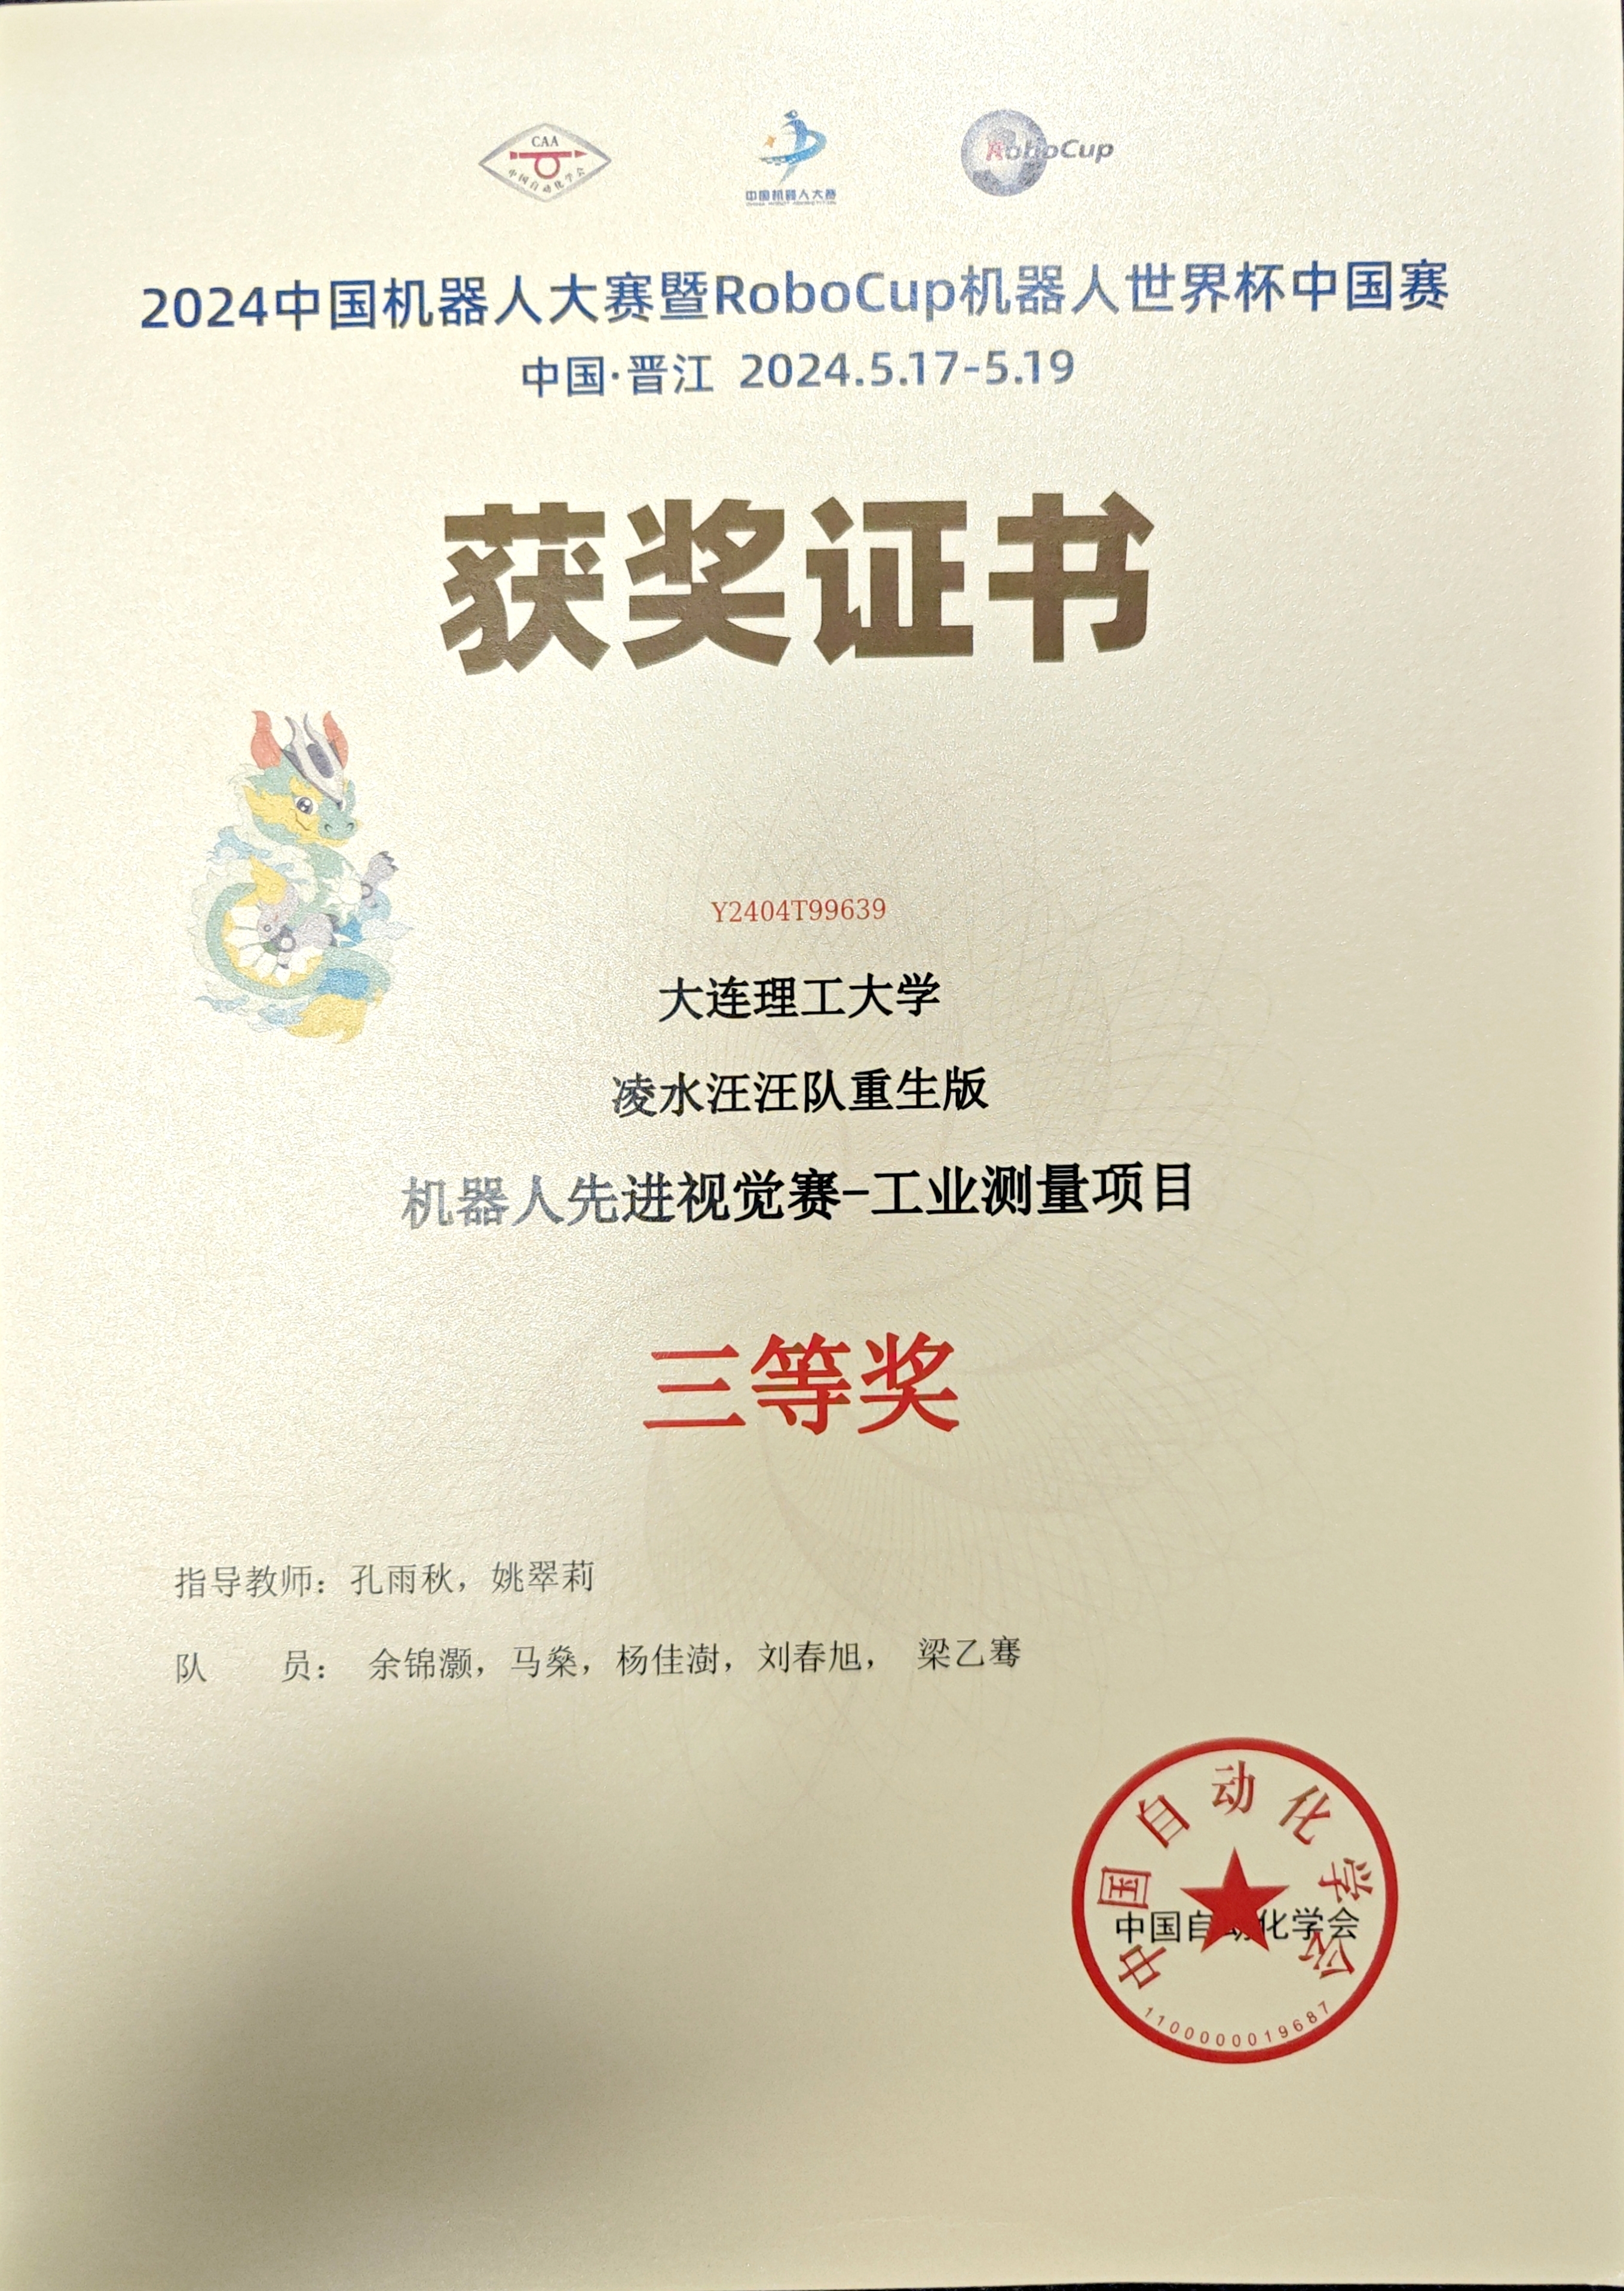
Award certificate

Open original ↗
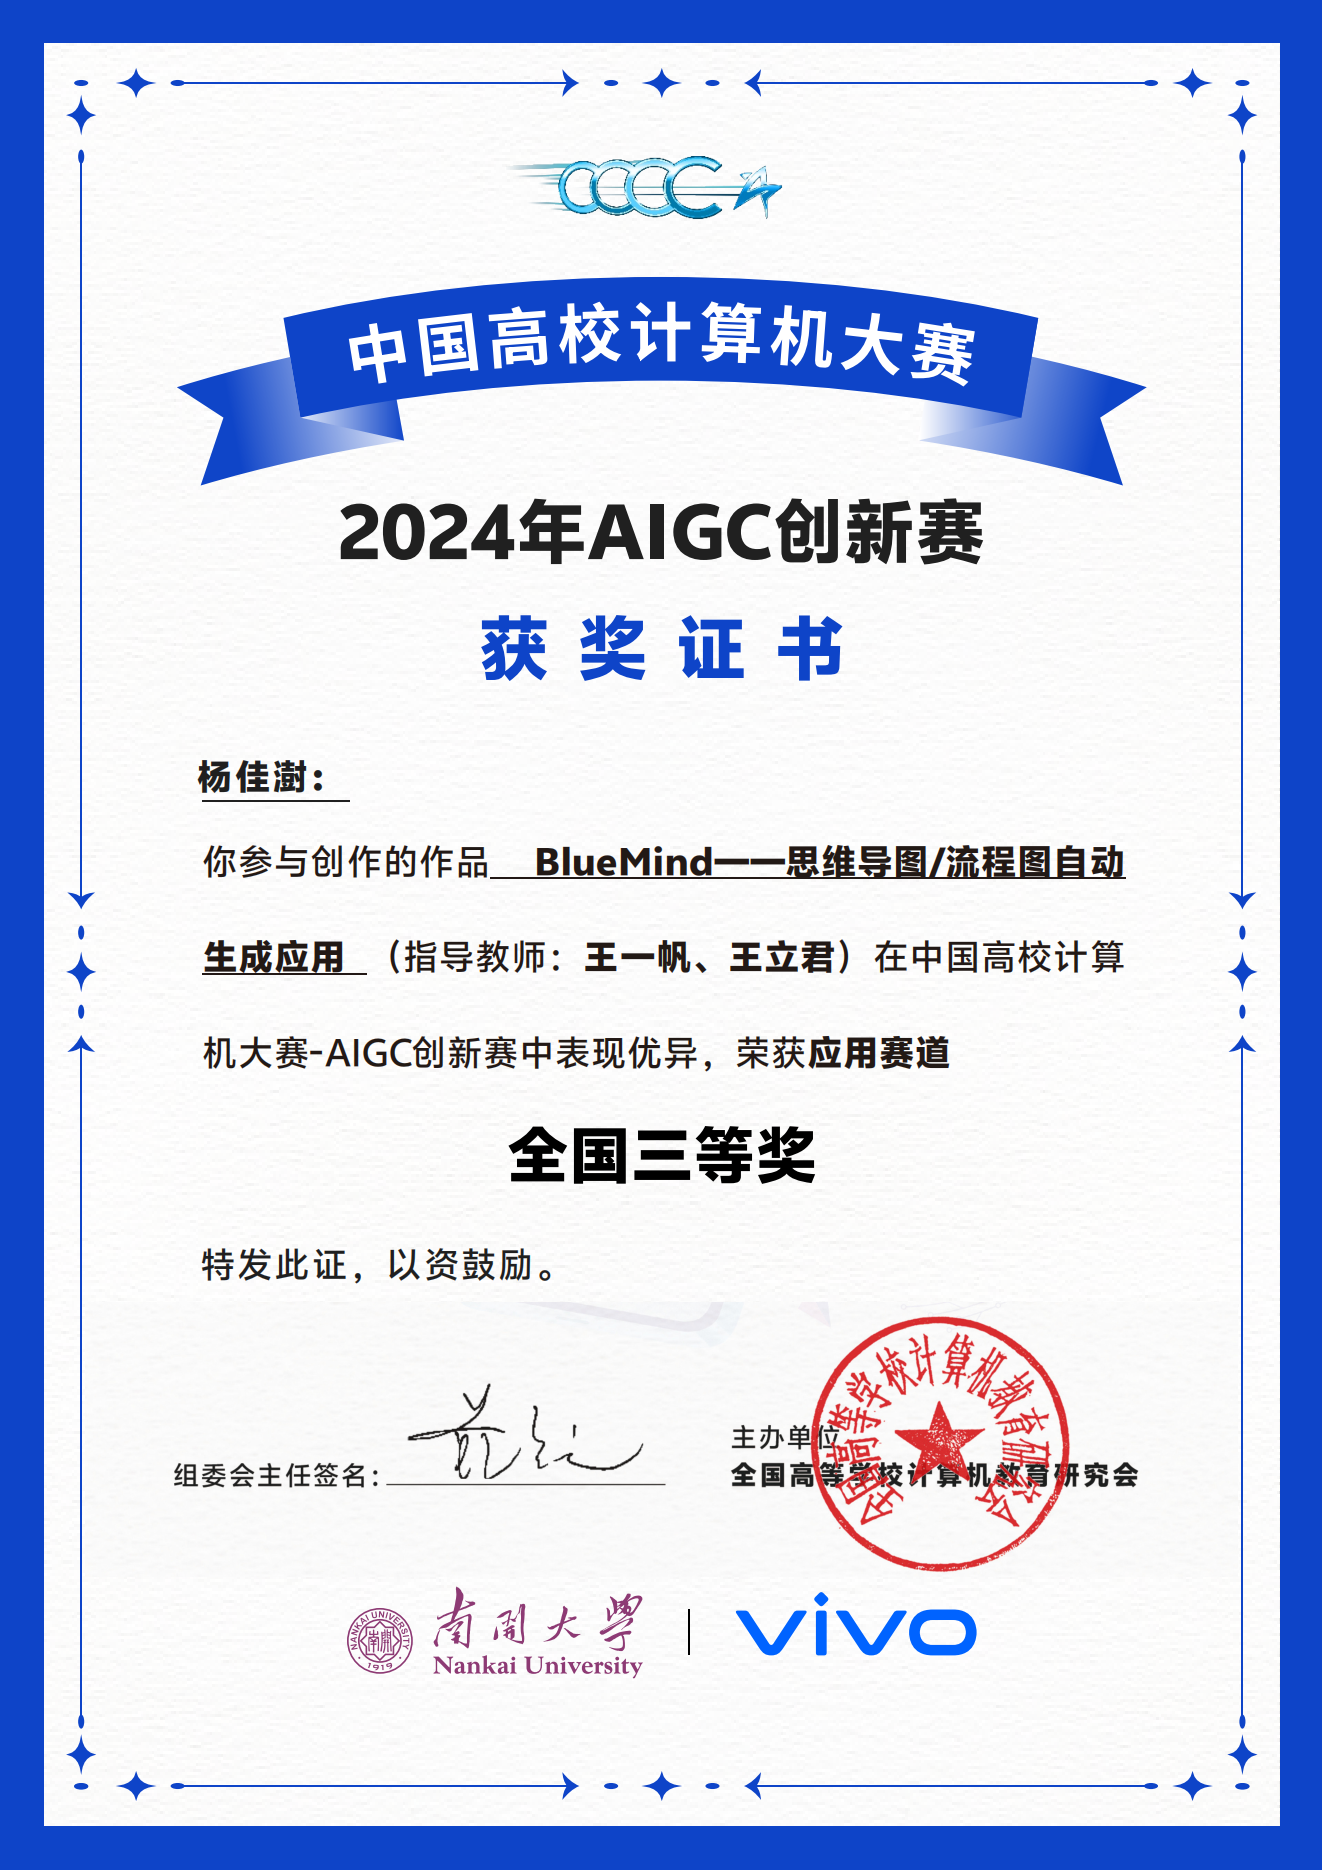
Award certificate

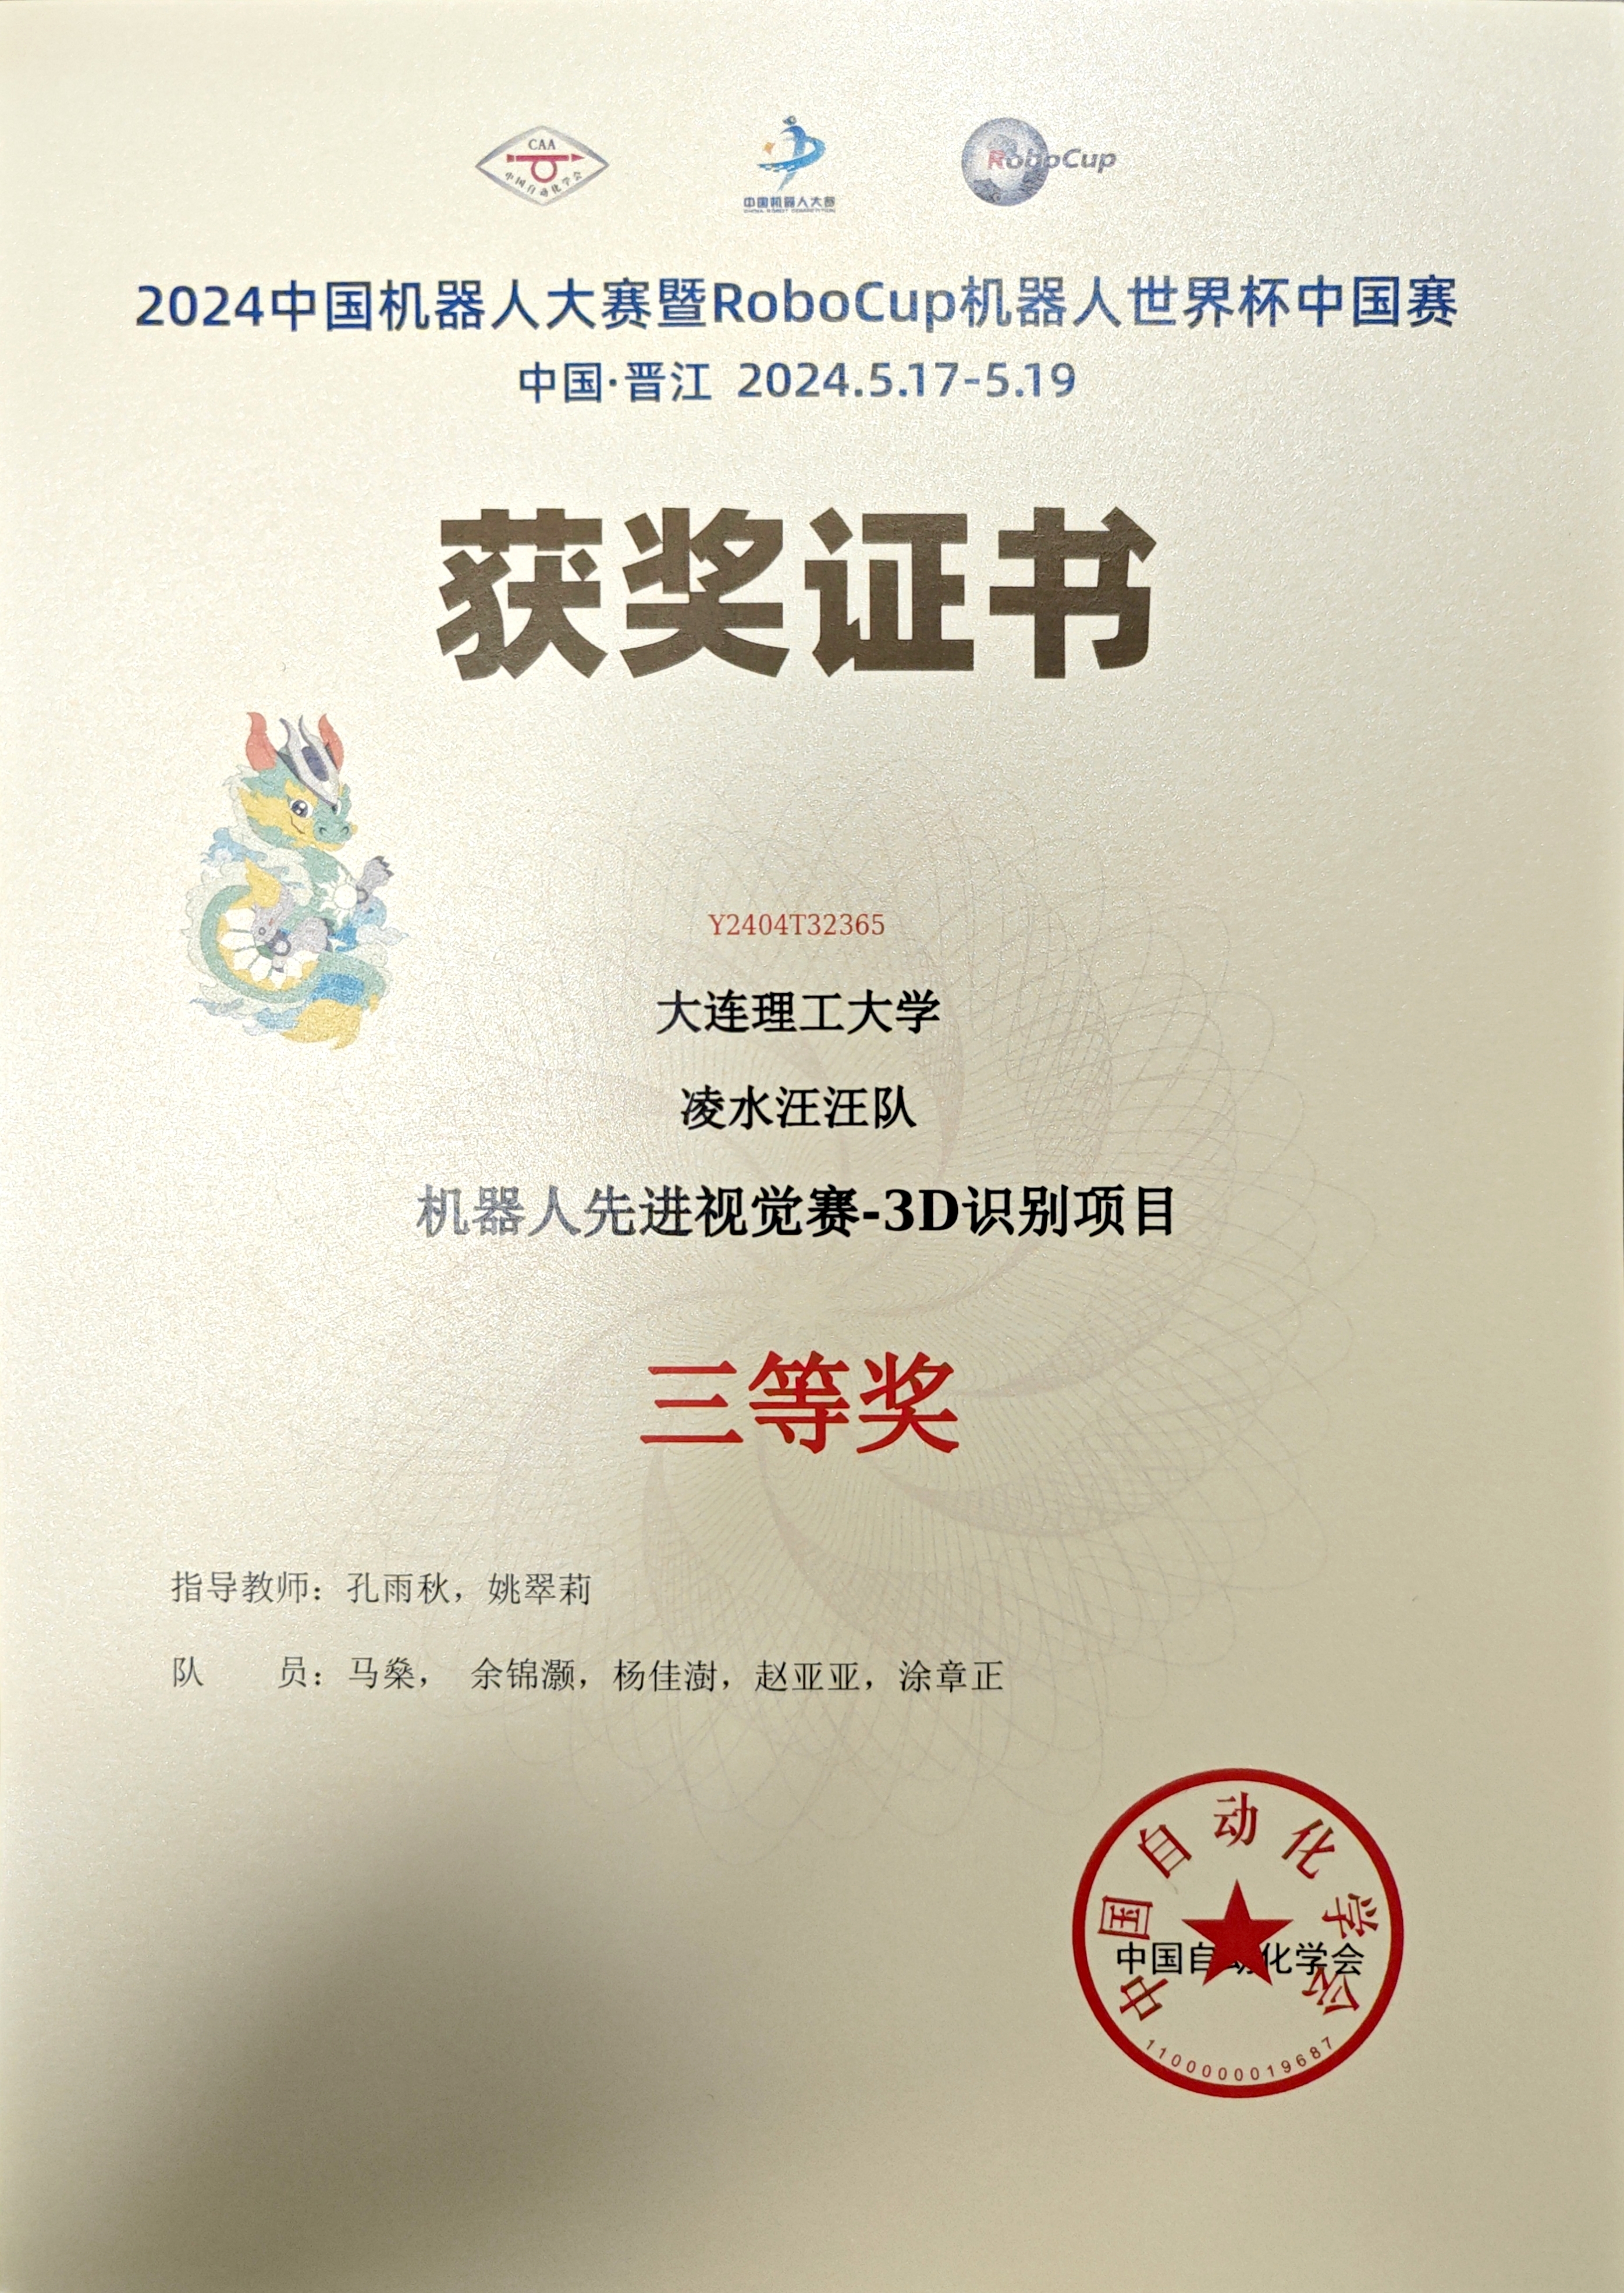
Research illustration

Open original ↗